

Research
Vision-Language-Action Models
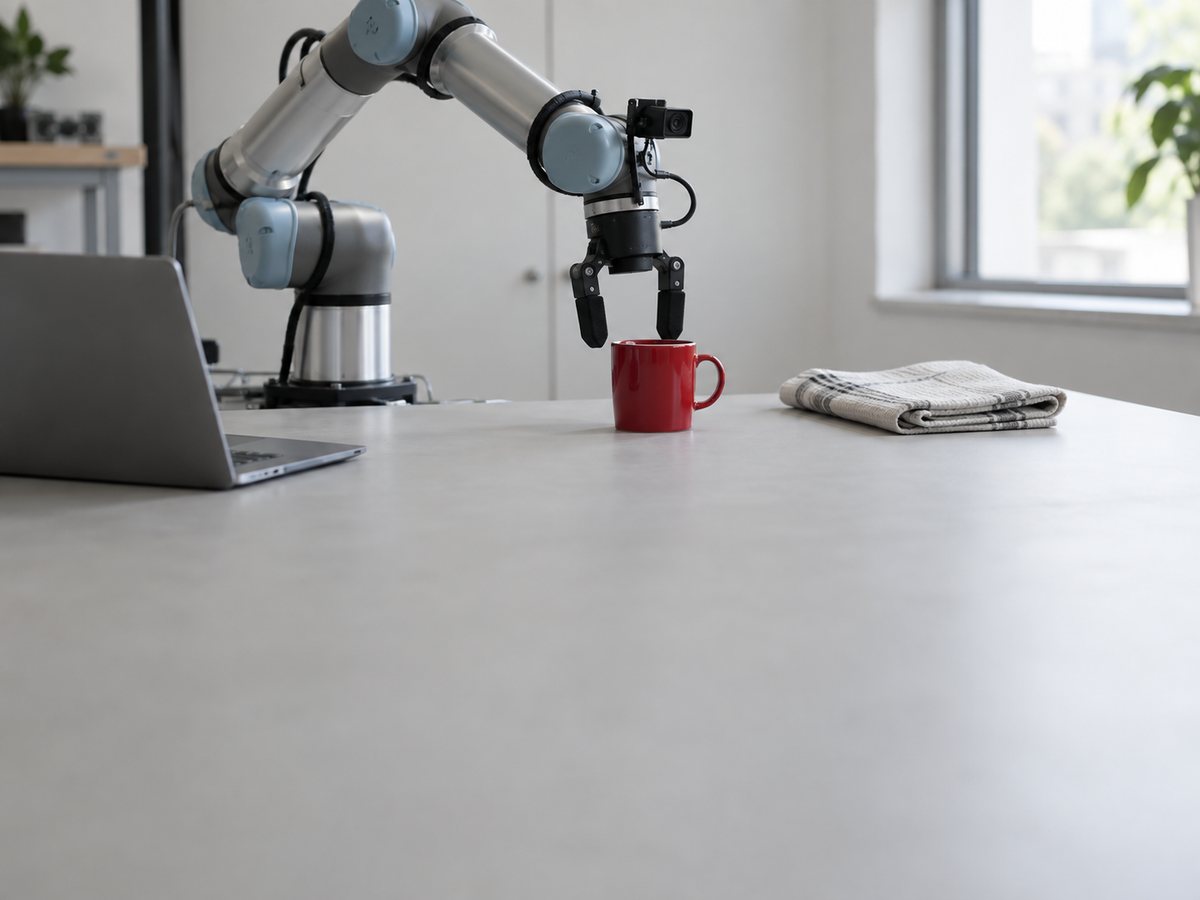
Models that map what a robot sees and is told directly into what it does, so one system generalises across tasks.
We build models that connect perception and language directly to action, so that a robot can be told what to achieve and work out how to achieve it. Rather than hand-engineering a controller per task, we train policies that share representations across tasks and generalise to instructions and objects they have not seen before.
The open questions we care about are how much of the mapping can be learned end to end, where explicit structure still earns its place, and how to keep a single policy competent as the set of tasks grows.